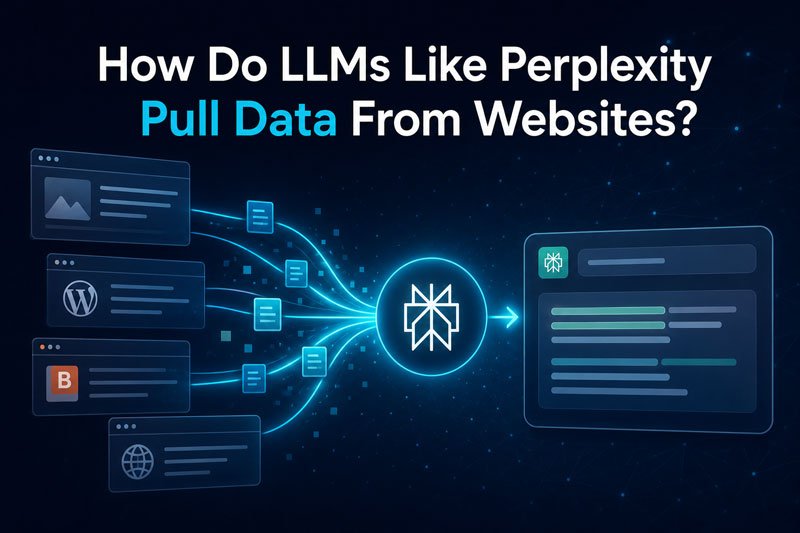
LLM-powered search tools like Perplexity pull data from websites by searching the live web, reading the pages they find, and then letting a language model write an answer with citations. Your site gets cited when the crawler can reach it, the page is easy to read, and the answer is clear and trustworthy.
You publish a post. Weeks later someone asks Perplexity a related question, and a competitor is cited instead of you.
Why does that happen? Once you see the mechanics, you can make deliberate choices that help. I’m Nazirul Islam Nakib, and this is how I explain it to clients.
One caution first: these systems change often, and companies don’t publish every detail. What follows is the widely understood picture, not inside information.
The basic process: retrieval, then writing
Tools like Perplexity don’t just recite what a model memorised in training. They use a pattern called retrieval-augmented generation (RAG).
Layer 1: retrieval. The tool searches for sources relevant to the question. It may use its own crawler and one or more search indexes.
Layer 2: synthesis. A language model reads the retrieved content and writes a single answer, usually with numbered citations.
The key point for site owners: the model can only use what retrieval gives it. If your page isn’t found, can’t be read, or isn’t clear, it never reaches the writing step.
What happens when someone asks a question
1. The tool interprets the question
It works out what the person actually wants, not just the words they typed.
2. It searches, often several ways
It may split the question into related sub-queries and search each one. This widens the pool of pages considered.
3. It reads the pages
This is where your technical setup matters. Clean HTML with readable text is easy to extract. Content that only appears after heavy JavaScript runs may come through incomplete.
4. It judges relevance
Pages that answer the question directly tend to be preferred over pages that talk around it.
5. It writes and cites
The model combines the best material into one answer and links to the sources it leaned on.
You can influence steps 3, 4 and 5. Here’s how.
What makes a page easier to cite
1. Let the crawlers in
Check your robots.txt file. Some sites block AI crawlers by accident, or on purpose.
Common user agents include PerplexityBot, GPTBot and ClaudeBot. Whether to allow them is your decision. If you want to be cited, don’t block them.
You may also see advice about an llms.txt file. It is a proposed convention, and support varies. It’s harmless to add, but don’t expect it to do the work on its own.
2. Make your content readable without JavaScript
Your main text should be present in the page’s HTML, not injected later.
Server-side rendering or static pages are safest for important content. See technical SEO.
3. Lead with the answer
Put a direct answer to the page’s main question in the first paragraph.
Then support it with:
- Descriptive H2 and H3 headings.
- Short paragraphs with one idea each.
- Numbered lists for steps.
- Tables for comparisons.
This helps people just as much as machines.
4. Add schema markup
Structured data tells crawlers what a page is: an article, a how-to, an organisation, an FAQ.
It helps systems read your content correctly, though it doesn’t guarantee citations. See schema markup.
5. Build authority outside your own site
Retrieval often pulls from forums, news, video, review sites and other third-party pages too.
When your brand is mentioned consistently and positively in trustworthy places, systems get a clearer picture of who you are. Read more in entity based SEO.
6. Keep important pages fresh
Live-search tools like current information. Review key pages regularly and update facts, examples and dates when they change.
Don’t change the date without changing the content.
Perplexity vs ChatGPT vs Google AI Overviews
Perplexity is search-first. Most answers involve a live web lookup, so recent, well-structured pages can be cited quickly.
ChatGPT can search the web when browsing or search is switched on. Without it, answers rely on training data, where long-term brand presence matters more.
Google AI Overviews sit on top of Google’s own index. Pages that already rank well and are clearly written are well placed.
Details differ, but the foundations are the same: a crawlable site, clear content and real authority.
A practical checklist
- AI crawlers allowed in robots.txt, if you want citations
- Main content visible in the HTML
- Direct answer in the first paragraph of key pages
- Clear H2 and H3 headings
- Schema: Article, Organization, and FAQ or HowTo where relevant
- Key pages reviewed and refreshed regularly
- Brand mentions building on trusted third-party sites
- Internal links connecting related pages
Frequently asked questions
Does Perplexity use Google?
It uses its own crawler and search index and may combine results from other sources. The exact mix isn’t fully public and can change.
How can I check if I’m being cited?
Ask questions in your niche on Perplexity, ChatGPT and Google, and note which sources appear. Repeat each month to see the trend. Server logs can also show AI crawler visits.
Will blocking AI crawlers hurt my Google ranking?
Blocking AI-specific crawlers is separate from Googlebot. But it does reduce your chance of being used as a source by those tools.
Can anyone guarantee AI citations?
No. You can improve your chances with clear content, a clean technical setup and real authority. Anyone promising a result is guessing.
What this means for your business
People increasingly ask AI tools for recommendations and explanations. Being a clear, trustworthy source puts you in those answers.
The work isn’t magic. It’s a technically clean site, content built to be understood, and a reputation that holds up.
That’s the heart of AI SEO. If you’d like to know where you stand, an AI visibility audit is the place to start, or contact me. You’ll find more on the home page.